Ask two questions: what counts as done, and how do we get there?
For work handed to an agent, I first separate two uncertainties: clarity of the goal and clarity of the process. Knowing what you want and knowing how to achieve it are different things.
A clear goal names the outcome, constraints, and acceptance criteria. A clear process has a reusable method. A workflow with many steps can be well understood; “make the system better” may leave both the outcome and the route unresolved.
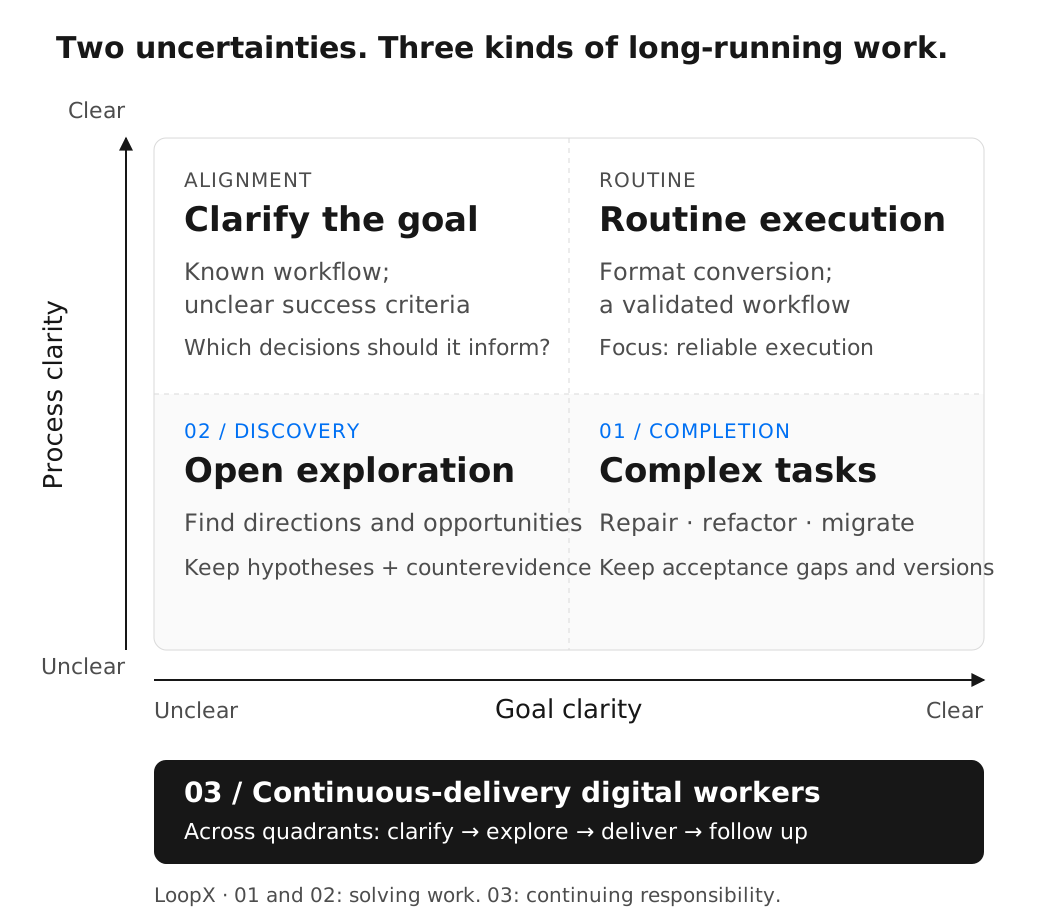
Top right: clear goal, known process. Convert data to a specified format or run a validated release workflow. Reliable execution matters here. A script or workflow can be enough for short work; waiting across days, recovering from interruption, or owning downstream results creates an additional continuity need.
Top left: known process, unclear goal. A team may know how to produce a weekly report without having agreed whose decisions it should inform. Clarify the audience, value criteria, and tradeoffs first. Speeding up a familiar process does not automatically make its output useful.
Bottom right maps to 01; bottom left maps to 02. The former knows the destination and must find a route. The latter also uses exploration to discover what is worth pursuing. An exploratory round can still define its question, evidence requirements, and stopping conditions; an unclear goal is not a mandate to run indefinitely.
03 is a continuing responsibility across quadrants. An agent maintaining a repository may clarify performance needs, investigate a bottleneck, complete a fix, and follow its pull request. It takes on both complex tasks and exploration, while remaining responsible when new feedback arrives.
Uncertainty determines what must persist.
Continuing responsibility determines for how long.
01 / Finish a complex task
“Implement a decoder that conforms to the specification” sounds definite. Yet after the visible examples pass, edge inputs, memory safety, or compatibility may still be missing. Start a new session, and previously confirmed failure conditions may disappear from context.
LoopX keeps the goal and its acceptance gaps continuous across turns, then carries new evidence into the next decision. The model implements and judges; domain validators check the result; the control plane records which results were accepted and which work remains.
Preserve more than completed steps: the current acceptance version, unresolved gaps, attempted repairs, and the artifact version each check evaluated. If the task list is exhausted but acceptance is unmet, replan. If a person changes compatibility requirements, a pass on the old version cannot establish acceptance under the new criteria.
The best-fitting tasks usually span repeated validation, waiting, or handoffs. Existing agents may already be enough for small work that can be accepted in one session; an added control plane must justify its overhead.
02 / Find a path through open-ended exploration
“Find a better algorithm” does not come with a fully specified task chain. Real progress may validate a hypothesis—or eliminate a promising-looking route. If only successful conclusions survive, the next run can easily repeat ideas that were already disproved.
Explore provides an optional evidence graph and bounded branch planning: nodes represent questions and findings, while relationships express supports, refutes, and leads_to. Planning suggestions still pass through normal execution boundaries; the graph neither launches workers nor grants spending authority.
Auto Research organizes this pattern as research work: select a topic, propose hypotheses, run experiments, evaluate independently, and produce a report. Existing protocols and commands provide a foundation, while the public showcase still contains blueprints and items awaiting validation. Real effectiveness must be demonstrated on specific tasks.
Exploration can be accepted by the uncertainty it removes: compare candidate routes, produce a reproducible experiment, rule out a hypothesis, or identify the evidence still missing. A well-supported negative conclusion can complete a bounded research round. A finite research deliverable can close out while a longer-term direction continues in another round.
Place RSI here, but keep the claim precise
When the object of improvement is the agent’s own tools, strategies, or harness, the work becomes self-improvement research. Changing its own code only creates a candidate; sustained improvement still requires independent evaluation, cross-task generalization, regression checks, and rollback.
Applying past experience to a later decision, automatically generating experiments, and modifying the harness are different levels. We can discuss an experimental path toward recursive self-improvement (RSI) here; we cannot equate “automatic iteration” with open-ended self-improvement already achieved.
03 / Own continuous delivery
For a pull-request or issue-fix digital worker, the job begins by deciding whether the issue is worth fixing. After delivery, CI, review feedback, branch changes, and the merge result still remain. New tasks keep arriving, and external facts keep changing.
Responsibility does not end when the patch is generated.
This synthetic scenario starts after a fix has been submitted while CI and review are still running. Choose an external state to see how the next step changes.
- External fact
- GitHub reports that checks are pending for the current revision.
- Domain state
- Record the pull request, revision, and check state; an unchanged observation does not create progress.
- Capability proposal
- Preserve the monitor and recovery condition, then wait for the result.
- Control-plane check
- Admit work by authority, budget, and eligibility; work outside the wait scope can still proceed.
- Meaning for people
- Stay quiet when nothing material changed, so polling does not become nagging.
This interactive diagram is a design explanation. It is not connected to a real repository and performs no GitHub operations.
Here, a “digital worker” means continuing responsibility, boundaries, memory, and a feedback loop. Its value should be judged by accepted fixes, reopenings and regressions, handling latency, delivery cost, and how often a person must repeatedly supervise it. Pull-request count and uptime are only process signals.
A continuing responsibility also needs rules for when to wake, when to stay quiet, and when to involve a person. New review feedback can become work input; unchanged pending CI does not need repeated interruptions. Missing authority, goal tradeoffs, or exhausted budgets need explicit stopping points. One repair can finish while the maintenance role continues; that role must also be pausable, revocable, and transferable.
Work moves between quadrants. State must follow.
Consider maintaining a service’s performance. “Make it faster” first requires agreement on workload, metrics, and compatibility constraints. Once the outcome is clear, the bottleneck still needs investigation. Finding a repair route turns the work into implementation and acceptance; submission brings review, feedback, and regression follow-up.
This is not a one-way progression. Feedback can change the goal; a counterexample can invalidate the route. A stable method discovered through exploration can become a routine workflow, while new conditions can send a workflow back into exploration. An agent must recognize whether the remaining issue is disagreement about the goal, uncertainty about the route, or simply waiting.
A task’s name does not determine its position; the information currently available does. Research with an agreed question, deliverable, and scoring rule can be managed as a task with clear acceptance. A refactor with a mature method can rely more on an established workflow. Both axes are continuous; the quadrants mark common work patterns.
Useful handoff state includes the current goal and constraints, why this route was chosen, rejected approaches, artifact and acceptance versions, and conditions for continuing or stopping. A chat summary or “step three completed” alone cannot carry these changes.
The same work may change models, sessions, or executors. Revisions to its goal, evidence of failure, and outstanding responsibilities should remain continuous. This is the shared place of a long-horizon control plane in all three scenarios.
The richer the domain, the clearer the division of responsibility must be
Authority and common lifecycleWhich goals and work items are valid, who may act, which authority and budgets apply, and how work is handed off, paused, and committed.
Domain continuityWhether this issue is actionable, which revision the pull request names, where CI and review stand, and which conclusions remain valid.
Outcome contract and judgmentTranslate domain facts into a verifiable next step: repair, wait, ask a person, or close out—and define acceptance for the scenario.
External I/O and executionCall repositories, tests, and tools; perform authorized actions; and read back the result. GitHub still owns the external facts about code, CI, and review.
For checks failing, a domain capability can propose a successor task to repair CI. The fact that a repair is needed does not itself grant repository write or merge authority. In an experiment, check state becomes metrics and held-out conclusions; the common claim, authority, and recovery rules should remain consistent.
That is the value of a capability: it captures recurring judgments and outcome contracts for a scenario without forcing every business stage into the Kernel.
When does a long-horizon control plane help?
The quadrants describe uncertainty. The need for continuity across turns determines whether additional state management helps. Exploration that can be accepted within an hour may not need a long-horizon system. A fully understood release process may need one because it spans days, handoffs, and external feedback.
- Complex tasks: changing sessions means explaining acceptance again, recovering repair progress, or rediscovering known gaps.
- Open exploration: several routes run in parallel, negative results disappear, and the next round needs evidence-based allocation rather than recollection.
- Continuing responsibility: tasks, reviews, or external outcomes keep arriving, leaving a person to act as dispatcher and follow-up manager.
These are concrete reasons to externalize state. After adding LoopX, check whether verified output increases, regressions and duplicated work decrease, and people spend less attention managing it. Count the additional execution and maintenance costs too.
My goal remains to have agents do more work while people spend less attention managing them. Separating exploration, execution, and continuing responsibility helps give each kind of work the right management—and reserve human judgment for decisions worth making.
Benchmarks: start with LHTB, then three supporting signals
Most benchmarks provide acceptance criteria, testing problem solving with a clear goal and an unknown route. Even a task that requires algorithm exploration has a specified deliverable and scoring rule. Choosing an open-ended research direction or maintaining an ongoing responsibility is a different level of work.
Start with recovery and regression across long-horizon domains, then use three software-engineering studies to examine continuation, delivery, and validation. The four studies differ in tasks, model settings, and measurement rules. Each needs to be read on its own terms; the current evidence does not establish a universal LoopX gain.
LHTB: what does LoopX accomplish beyond Plain and native Goal?
GPT-5.6 Sol / max · 46 matched tasks · one effective run per task-arm cell
What LHTB tests: Long-Horizon Terminal-Bench asks an agent to complete hundreds of dependent terminal actions in a stateful container. Its 46 tasks cover nine categories: software and reverse engineering; scientific computing; earth, climate and energy; multimodal work; research reproduction; systems, performance and security; games; APEX professional workflows; and logic puzzles. Examples include framework migration, paper reproduction, investment-banking deliverables and playing 2048. Categories and representative tasks →
How it scores: hidden verifiers grade final artifacts or replayable outcomes on a 0–1 reward scale. This study counts ≥ 0.95 as solved, reporting average progress and full acceptance separately.
| Execution | Mean reward | Solved / 46 |
|---|---|---|
| Plain | 0.4218 | 7 |
| Native Goal | 0.4475 | 4 |
| LoopX Heartbeat (1.0.3) | 0.4948 | 7 |
Observation: against Plain, LoopX gains 0.0731 mean reward (17.3%), with 17 wins, 13 ties and 16 losses, and the same solve count. Against native Goal, it gains 0.0473 (10.6%), with 23 wins, 13 ties and 10 losses, and 7 solves versus 4. Counts compare published unrounded scores strictly; higher mean reward does not imply better results on every task.
Where gains cluster: in post-hoc groups based on task demands, research/modeling (4 tasks) gains +0.2802 / +0.2179 mean reward over Plain / Goal; logic puzzles (4 tasks) gain +0.2739 / +0.1374. Research stays positive without Tabular. Sokoban retains solved levels, Rush Hour requires a route ledger and replay checks, and Tabular requires experiments and validation—promising conditions to test.
Where the advantage is unclear: multimodal analysis (6 tasks) yields −0.0034 / +0.0058; science and simulation (7 tasks) yield +0.0161 / +0.0099. Games are mixed: 2048 improves, but Snake trails Plain. APEX law trails Goal, and DuckDB scores 0 versus about 0.770. Continuation cannot substitute for perception, domain judgment or correctness checks.
Insight: prioritize tasks where the next step can be checked and useful progress retained. The median paired delta across all tasks is 0 against Plain and about 0.0003 against Goal: mean gains are concentrated. Groups contain only 4–7 tasks and are not an official task mapping. Prompt structure suggests explanations, but does not establish the mechanism behind a trial’s score. Nine groups: counts, wins/ties/losses, sensitivity and task instructions →
Boundary: LoopX here is the study’s 1.0.3 fresh-exec Heartbeat. Execution settings differ, replacement trials include longer limits, and there are no repeated seeds. LoopX records $551.73, above the Plain / Goal estimates of $212.97 / $344.25. Accounting also differs; equal-budget efficiency gains are not established.
Full study: two baselines, gains and losses, 46 tasks, and historical context →
SWE-Marathon: continuation must close real gaps
GPT-5.6 Sol / high · 15 matched tasks · 3 retained modes, one run per cell · timeout factor 0.3
Observation: native Goal completed 4/15; Heartbeat completed 5/15. Total cost for the two groups rose from $533 to $830, about 56%.
Insight: in the zstd case, continuation addressed acceptance beyond the visible tests; in the Excel case, repeated continuations still did not finish. The questions worth pursuing are which gap a next run closes and whether that gain justifies the added cost.
Boundary: each cell has one run and several mechanisms change together. There are both useful cases and ineffective continuation; stable gains or cost advantages have not been established.
Full study: results, cost, and positive and negative cases →
DeepSWE × Sol: decompose the completion difference
Script default GPT-5.6 Sol / xhigh · 113 tasks · historical best-valid aggregation
Observation: bare Codex, native Goal, and Heartbeat completed 54, 60, and 70 tasks respectively. Heartbeat completed ten more than Goal, but its default time window was also longer.
Insight: the source separates “continue execution” from “deliver a valid result”: even when a worktree contains code, the collector may still receive an empty patch. Recovery, patch delivery, and independent acceptance should be examined separately before attributing their contribution to the completion difference.
Boundary: this is the best valid result per task, not a single-run pass rate; budgets differ, and attempts and cost are not fully disclosed. Unreverified merged scores cannot be treated as a net gain at equal budget.
Full study (Chinese): historical results, recovery, and delivery mechanics →
DeepSWE × V4 Flash max: let counterexamples change the implementation
DeepSeek V4 Flash / max + Codex · frozen 113 tasks · Goal and LoopX compared under the same hint condition
Observation: LoopX had about two percentage points higher feature coverage per task on average. In a post-hoc long-duration slice where both groups had hints, completions rose from 12/29 to 14/29 while cumulative duration fell 16.4%.
Insight: the selected cases differ in whether failure counterexamples are retained and whether external contracts can overturn implementation assumptions. Validation matters when it changes the fix and triggers revalidation—not merely when it adds more checks.
Boundary: coverage is not success rate; the long-duration slice is post-hoc, and elapsed time includes successful and failed runs. Local findings cannot be generalized into an overall gain or equal-quality speedup.
Full study: requirement coverage, behavior cases, and the long-duration slice →
Recover progress, preserve working results, and check whether continuation closes acceptance gaps.
The four studies offer local positive observations while exposing regressions, cost, and attribution problems. Matched budgets and repeated experiments should examine recovery, rollback, delivery, and counterexample-driven repair separately.
Withdrawn SSH Goal and Codex CLI scores and conclusions from SWE-Marathon and DeepSWE × Sol are not used in these comparisons.
Evolution: add one verifiable capability at a time
- One-shot execution → recoverable long-running taskRecover the goal, evidence, and next step across sessions and process interruptions. First prove one thing can be finished reliably.
- Generic task → domain delivery and explorationUse issue-fix and research work for real outcomes, preserve domain state, and define what makes a result valuable.
- One agent → small-team collaborationFirst have two or three workers complete two rounds of dependent delivery: receive artifacts, accept independently, absorb corrections, and return results.
- Local collaboration → continuous work across hostsValidate shared state, authority revocation, stale-worker isolation, network failure, and shared budgets. Successful registration is not proof of collaboration.
- Sustainable operation → measurable improvementUse outcome feedback to improve selection, memory, and strategy; prove gains through controlled experiments, held-out validation, and rollback. Qualify scaling separately.
These are a build order and validation targets, not a completion checklist. Foundations, partial implementations, blueprints, and end-to-end qualification should be read separately.
I want what we hand to an agent to evolve from a single instruction into a work agreement it can keep fulfilling.
That agreement should remain legible and editable to people, actionable to agents, and auditable through evidence after failure.
Public sources and further reading
The technical content is derived only from public repository material. Source and data links are pinned to the revisions read for this article; historical experiments retain their own versions. This page introduces no new experimental results.
- LHTB: compared with Plain and native Goal; public aggregates for 46 tasks; setup and evidence boundary; mechanisms and cases reported in the brief; official benchmark. See the study for contributor attribution.
- SWE-Marathon: continuous self-verification; setup, positive and negative cases, and limitations; public aggregate data. See the study for contributors and case provenance.
- DeepSWE × Sol: from continued execution to valid delivery (Chinese). The standalone brief covers historical results over 113 tasks, mechanism diagrams, and pinned primary sources; research archive contribution: @gwh6669999, #4502.
- DeepSWE × V4 Flash max: from hints to behavior; disclosure boundary; charts, cases, and metrics at the pinned revision.
- Explore: evidence graphs, planning, and authority boundaries.
- Auto Research: public blueprint and command path.
- PR / Issue Fix: how State Kernel and domain state work together (Chinese).
- Overall roadmap: product goals and independent acceptance milestones.
- From one-shot agents to long-horizon control; LoopX: Native Kanban for long-running agents.